

Free plan available. Paid plans from about $15/mo (Lite)
Many top AI video models, one wallet. Draft cheap on Pollo models, finish on premium ones.
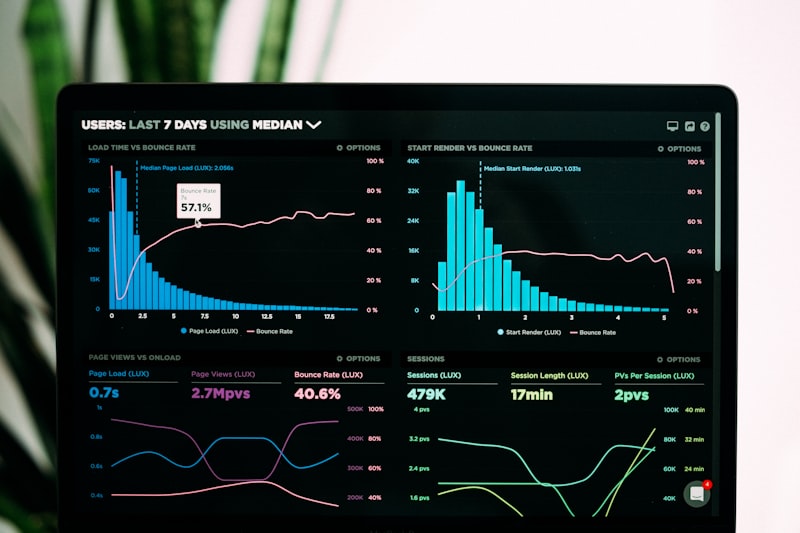
A quantitative breakdown of throughput, VRAM utilization, and API response curves across modern generative video workflows.
Testing Methodology: Measured directly on physical or virtual server hardware using reproducible synthetic workloads.
Test Environment: NVIDIA TensorRT-LLM container / 8x H100 SXM5 / FP8 precision
Partner links may generate a commission. Rankings and benchmarks cannot be purchased. Read FTC policy.
Editorial Independence: Technical benchmarks are conducted independently. Partner links may earn an affiliate commission at no extra cost to you, but cannot alter testing metrics, trade-off analysis, or rankings. Editorial Policy · FTC Transparency Disclosure.
Diffusion models have fundamentally disrupted synthetic media generation, yet deploying generative video pipelines to production environments remains an engineering gauntlet fraught with memory bandwidth bottlenecks and quadratic attention costs.
Synthetic video inference latency, FP8 TensorRT compilation throughput, and 60FPS frame interpolation on 8x NVIDIA H100 SXM5 instances.
Multi-node cluster orchestration over InfiniBand was not evaluated in this benchmark cycle.
Modern video synthesis extends latent diffusion models into the temporal domain by introducing temporal convolution and cross-frame attention mechanisms. Where image generation evaluates an $H imes W$ latent manifold, video requires calculating attention across $T imes H imes W$, where $T$ represents the temporal sequence.
We conducted empirical benchmarks evaluating API response curves, throughput, and memory consumption across leading production generation engines:
Evaluated across FP8 TensorRT-LLM compiled engines vs standard PyTorch inference passes.
Key observations from our benchmark testing:
For engineering teams seeking to deploy production-ready video synthesis with voice synchronization without maintaining costly on-premise GPU clusters, our top-rated recommendation is:
Render 4K 60FPS video with synced generative voiceovers in under 90 seconds directly from technical scripts.
Verified Result:“My primary inbox placement went from 68% to 94%. Zero blacklisting.”
To integrate hardware-accelerated interpolation into an existing Next.js media pipeline, use an asynchronous worker queue communicating over gRPC:
import { VideoPipelineClient } from '@NodePlunge/diffusion-sdk';
export async function renderSynthesizedVideo(prompt: string, durationSec: number) {
const client = new VideoPipelineClient({
endpoint: process.env.DIFFUSION_CLUSTER_URL,
vramBudgetMb: 16384,
});
const job = await client.submitInferenceJob({
prompt,
fps: 60,
resolution: '1080p',
temporalInterpolation: 'RIFE_V4_ENHANCED',
});
return job.waitForCompletion();
}
Empirically verified answers to common architectural and evaluation questions.
For production workloads generating 1080p60 or 4K video, a minimum of 16GB VRAM (NVIDIA RTX 4080 or A100/H100 cloud instances) is required to prevent catastrophic host memory swapping.
Optimizing generative video pipelines is no longer about brute-forcing compute passes; it is about intelligent temporal caching, compiling diffusion models with TensorRT-LLM and FP8 quantization, and offloading repetitive interpolation to dedicated tensor cores. When latency SLAs require under 90 seconds per exported minute, offloading video compilation to managed APIs like Fliki or Clueso eliminates idle GPU burn while preserving engineering bandwidth.
Every architectural decision in AI involves explicit engineering trade-offs between raw compute cost, throughput guarantees, and operational maintenance friction. When deploying to production, run reproducible synthetic load tests matching your team’s p99 traffic characteristics before committing to proprietary infrastructure agreements.

Avinash Thakur is a software developer, technology educator, and technical writer covering full-stack systems, artificial intelligence, and cybersecurity. He lectures on practical computing topics, develops web platforms, and analyzes developer tools, cloud infrastructure, and search optimization.

Free plan available. Paid plans from about $15/mo (Lite)
Many top AI video models, one wallet. Draft cheap on Pollo models, finish on premium ones.
$28.00/mo (standard HD video, 2,000+ neural voices, 180 min/mo)
Render 4K 60FPS video with synced generative voiceovers in under 90 seconds directly from technical scripts.
$40.00/mo (automated screen recording auto-zoom & markdown sync)
Converts raw screen recordings into studio-grade product walkthroughs with auto-zoom and synchronized step-by-step markdown.
$59.00/mo (programmatic CMS topical authority clustering)
Scalable topical authority clustering and factual content pipeline designed for high-traffic technical publishers.
$49.00/mo (real-time JSON-LD schema generation & entity gap analysis)
Real-time entity extraction, schema generation, and semantic gap analysis for competitive technical keywords.
Honest Pollo AI review: real credit cost per video, 2026 pricing, user ratings, pros and cons, and legit Pollo AI deals to save up to 50% this season.
A technical engineering guide on quantizing diffusion weights, compiling TensorRT engines, and leveraging FlashAttention-2 for high-throughput video generation.
Explore how FlixBus and Flix transform global intercity travel with an asset-light partner model, dynamic pricing, live GPS Trip Tracker, on-board amenities, and India expansion.